Language Model Research
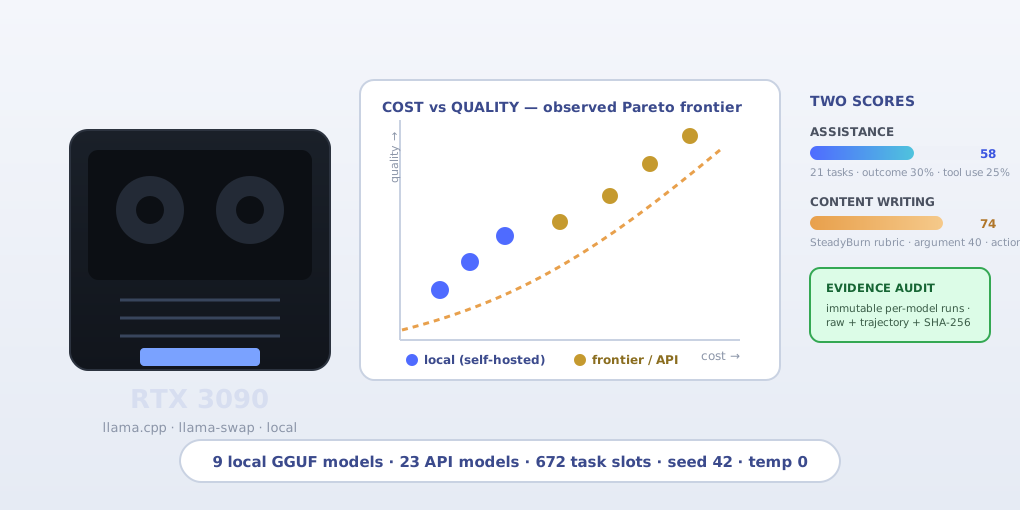
Language Model Research is my own benchmark for self-hosted LLMs running on an RTX 3090: a two-suite test bench measuring assistance capability (21 information-worker tasks per model, weighted outcome/tool-use/grounding/state/English/safety/efficiency) and content writing (scored against the SteadyBurn editorial rubric), with the automation and results published to a live dashboard.
Open the dashboard · Source on GitHub
Highlights
- Two deliberately separate scores — assistance and content writing are never merged, because they measure different work and a model can excel at one and fail the other.
- Strict, reproducible protocol: one model loaded at a time, unloaded buffer between switches, temperature 0, seed 42, 768-token turn cap, six-turn tool-loop ceiling; 9 local GGUF models + 23 OpenRouter models across 672 task slots.
- Evidence you can audit: immutable per-model run bundles (raw results, trajectory, config, lineage, manifest, SHA-256 hashes) and a run explorer that labels comparisons directly comparable / directional / not comparable.
- Decision-first dashboard: a cost-versus-quality scatter with the observed Pareto frontier — local models against frontier APIs — plus readability and cost views; fully static, no server or API key.
- Operator monorepo: durable PostgreSQL queue, CQRS event sourcing with live event history, local GGUF worker + OpenRouter worker, daily model discovery, and a publisher that rebuilds and commits the static pages.